Handling Race Conditions: Optimistic vs. Pessimistic Locking Strategies
The retry storm is the failure mode nobody warns you about
If you have ever seen a checkout system reject a payment with a generic "please try again" message during a flash sale, you were probably watching optimistic locking do exactly what it was designed to do — catch a conflict at commit time and refuse the write. The choice between that approach and its opposite, taking a lock before you touch anything, is not a matter of taste. It changes your throughput ceiling, your deadlock exposure, and what your application code has to handle when things collide.
Both strategies exist to solve the same problem: two transactions read the same row, both compute a new value from what they read, and whichever writes last silently overwrites the other's work. This is the lost update anomaly, and neither READ COMMITTED nor REPEATABLE READ isolation prevents it by default in PostgreSQL or MySQL — you have to choose a locking strategy on top of whatever isolation level you're running.
Pessimistic locking blocks first and asks questions never
Pessimistic locking takes an exclusive lock on a row the moment you intend to modify it, before you've done any of the work. In PostgreSQL this is SELECT ... FOR UPDATE, which the documentation describes plainly: it causes the retrieved rows to be "locked as though for update," and any other transaction attempting UPDATE, DELETE, or another SELECT FOR UPDATE on those same rows blocks until the first transaction ends, whether by commit or rollback. Nobody else gets to modify that row, or even queue up a conflicting lock, until you're done.
SQL Server does the same thing through table hints rather than a dedicated clause:
The UPDLOCK hint takes an update lock immediately on read, and ROWLOCK keeps the lock scoped to the row rather than escalating to the page or table — under the default READ COMMITTED isolation, other transactions can still read the row with a plain SELECT, but any transaction trying to acquire its own UPDLOCK blocks until yours releases. MySQL's InnoDB engine implements the same idea through standard row-level locking with shared and exclusive locks, described in Percona's own conference material on InnoDB internals as the textbook "pessimistic" approach.
The part that catches people off guard is what happens under REPEATABLE READ in InnoDB specifically. To stop phantom rows from appearing mid-transaction, InnoDB doesn't just lock the rows a query returns — it locks the gaps between index records too, so nothing can be inserted into that range while you hold the lock. MySQL's own documentation calls gap locks "purely inhibitive," meaning their only job is to block inserts into the gap, and two transactions can hold gap locks on the very same gap at the same time without conflict. That sounds harmless until each transaction's held gap lock blocks the other's pending INSERT, and now you have a deadlock that has nothing to do with the rows either transaction actually cares about. This is, by a wide margin, the most common source of "impossible" deadlocks reported against InnoDB, and switching to READ COMMITTED — which drops gap locking for plain index-record locks — is the standard mitigation when your application doesn't actually need repeatable-read semantics.
Why lock ordering, not lock scope, decides your deadlock rate
A deadlock happens when transaction A holds a lock B is waiting for, while B holds a lock A is waiting for, and neither can proceed. SELECT FOR UPDATE is not, on its own, protection against this — a single SELECT ... FOR UPDATE statement returning multiple rows acquires those locks one at a time, in whatever order the query plan produces, so it's entirely possible for the statement to already hold some of the rows it needs when it blocks waiting for another, and for a second transaction locking the same set in reverse order to complete the cycle.
PostgreSQL detects the resulting deadlock automatically, checking for it roughly once per second by default, and resolves it by aborting one of the two transactions with a deadlock_detected error so the other can proceed. InnoDB does the same thing immediately rather than on a timer, and the client sees this exact string:
InnoDB's own documentation specifies that it tries to pick the smaller transaction as the victim, where transaction size is measured by the number of rows inserted, updated, or deleted — so the one that has done less work gets rolled back, not the one that started first. The innodb_lock_wait_timeout setting, which defaults to 50 seconds, is a separate mechanism: it only kicks in if you've disabled deadlock detection entirely, which InnoDB's manual notes is sometimes done on very high-concurrency systems where the detection overhead itself becomes the bottleneck.
The fix that every primary source converges on is the same one: acquire locks in a consistent order across every code path in your application, typically by sorting row IDs ascending before you begin locking them. If transaction A always locks account 1 before account 2, and transaction B does the same, a circular wait becomes structurally impossible — one of them will simply get there first and the other will wait, not deadlock. This has to be enforced in application code; the database has no way to know that your two unrelated UPDATE statements are conceptually the same operation run in a different order.
Optimistic locking never blocks, and that is also its problem
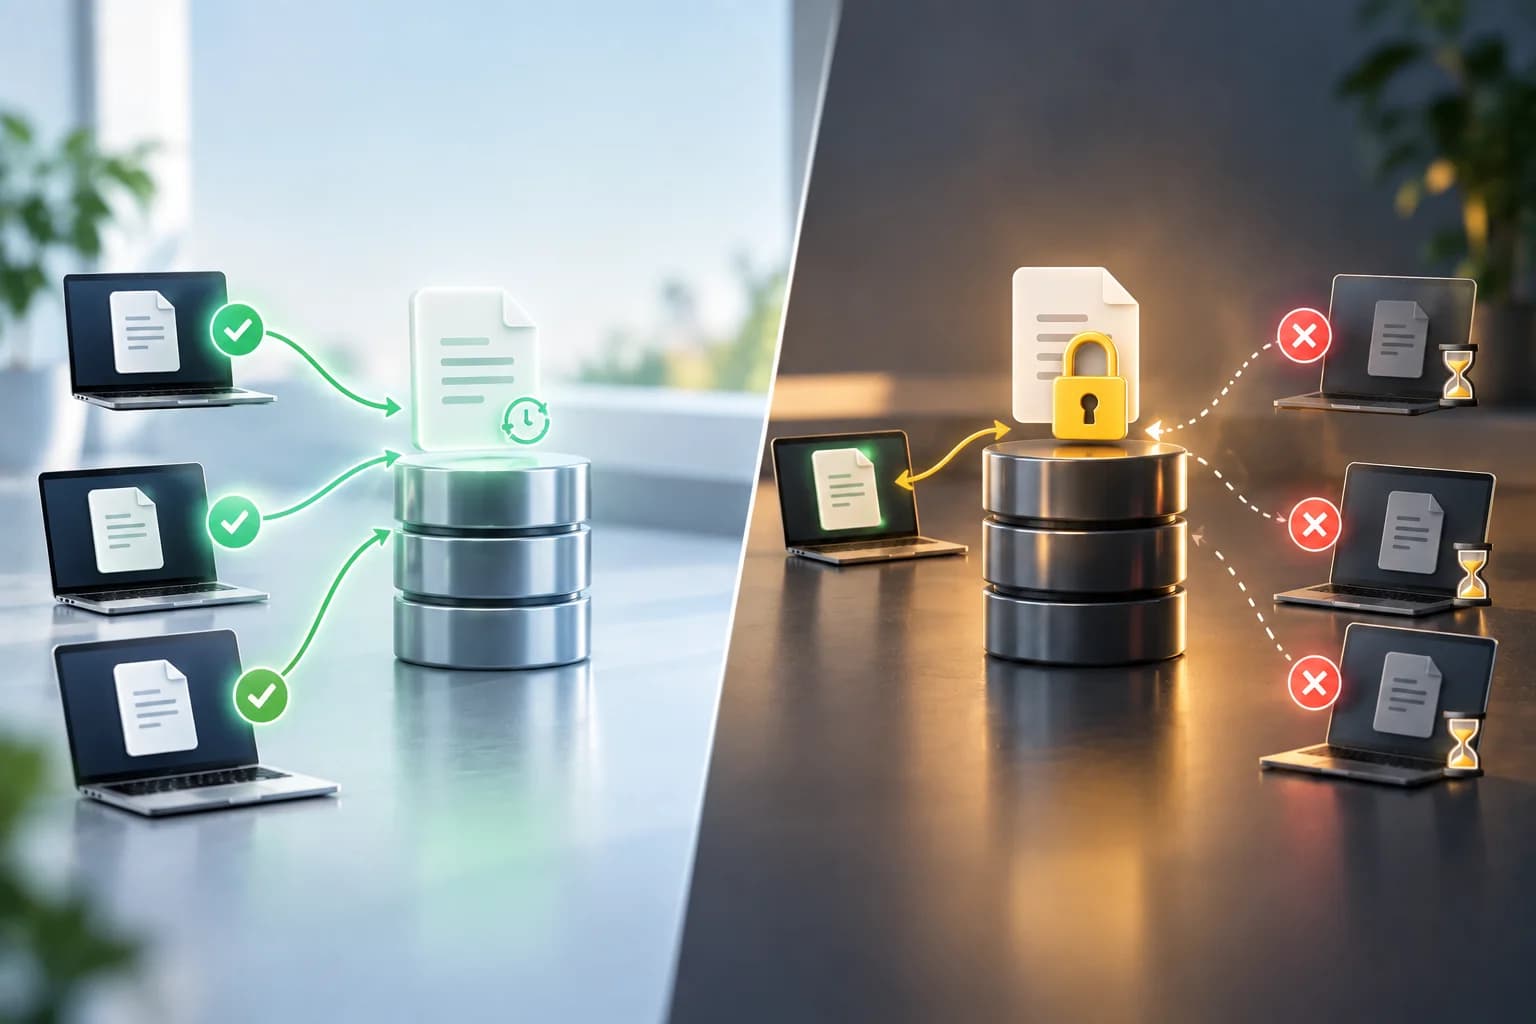
Optimistic locking assumes conflict is rare, so it takes no lock at all while you read. Instead, it stamps a version marker on the row and checks at write time whether that marker still matches what you read. The mechanism is the same across engines: a monotonically increasing integer, or in SQL Server's case an 8-byte rowversion column that the engine updates automatically on every modification without needing a trigger.
In JPA and Hibernate, this is a single annotation:
Hibernate includes the version in the WHERE clause of every generated UPDATE, something like UPDATE products SET name = ?, version = ? WHERE id = ? AND version = ?. If the row's version has moved since you read it, zero rows match the WHERE clause, Hibernate detects that the affected row count came back as zero, and it throws OptimisticLockException — wrapping the lower-level StaleObjectStateException if you're using the native Hibernate API rather than plain JPA. Note the mechanism is entirely a side effect of the row count, not a special database feature: any language's ORM, or raw SQL, can implement the identical pattern by checking UPDATE ... WHERE id = ? AND version = ? and inspecting whether it affected one row or zero.
One thing the Hibernate documentation is explicit about, and that trips people up in code review constantly: the automatic version check only fires when Hibernate flushes a managed, already-loaded entity. If your update path re-fetches the entity fresh inside the same method and compares versions manually, or if you're bypassing the persistence context with a detached object, you have to implement the version comparison yourself — Hibernate will not retroactively apply optimistic locking to code that doesn't go through its managed entity lifecycle.
What "no locking overhead" actually costs you
The trade-off is not free, it just moves the cost from blocking time to wasted work. At low contention, optimistic locking wins outright: there's no lock acquisition, no waiting, and reads never block writes or each other. As the number of concurrent writers targeting the same rows grows, the retry rate climbs, and every retried transaction has already burned CPU, I/O, and application-layer round trips doing work that gets thrown away.
A useful way to reason about the crossover is the throughput model laid out by engineers who've had to tune this in production: pessimistic throughput is bounded by how long each transaction holds its lock, roughly , which gives you a flat, predictable ceiling regardless of contention. Optimistic throughput under contention degrades as , where is the number of concurrent writers and the number of contended rows — as grows relative to , the wasted-retry term dominates and throughput falls off. The commonly cited crossover point, where pessimistic locking starts outperforming optimistic, is a conflict rate somewhere in the 10 to 20 percent range, though the exact figure depends heavily on how expensive a single retry is in your specific workload — a retry that just re-runs a cheap UPDATE is nothing like a retry that has to redo an external API call first.
This is also why optimistic locking is the wrong default for anything with genuinely high contention on the same row — a hot inventory counter during a flash sale, a single ledger balance hit by hundreds of concurrent transfers. You will get correctness, because the version check never lies, but you'll also get a flood of OptimisticLockException retries that saturate your application threads doing work that gets discarded on every collision. That specific failure pattern — an app server pegged at high CPU while database utilization looks fine — is one of the more diagnostic signs that optimistic locking was applied to a hot row it was never suited for.
Matching the strategy to the actual contention pattern
| Dimension | Pessimistic locking | Optimistic locking |
|---|---|---|
| Lock taken | On read, held until commit/rollback | None; checked only at write time |
| Read/write blocking | Writers block writers; readers usually unaffected under READ COMMITTED |
Nothing blocks; reads and writes proceed freely |
| Failure mode | Lock wait, then possible deadlock | OptimisticLockException / zero-row update, requiring app-level retry |
| Best contention profile | High conflict rate on the same rows | Low conflict rate, read-heavy workloads |
| Deadlock risk | Real, mitigated by consistent lock ordering | None — no locks held, so no circular wait is possible |
| Typical mechanism | SELECT ... FOR UPDATE (Postgres), UPDLOCK/ROWLOCK (SQL Server), InnoDB row locks |
Version/rowversion column checked in WHERE clause |
The decision genuinely comes down to how often two transactions are going to fight over the same row, not to a general preference for one paradigm. A banking ledger where a handful of savings accounts get hit by scheduled interest postings once a night is a poor candidate for pessimistic locking — you'd be serializing transactions that almost never actually conflict. The same ledger's central clearing account, hit by thousands of concurrent transfers during a settlement window, is a poor candidate for optimistic locking, because you'd be manufacturing a retry storm on a row you know in advance is hot.
There's a middle position worth naming because it gets skipped in most comparisons: SELECT FOR UPDATE SKIP LOCKED, which lets a transaction grab whichever unlocked rows are available and simply skip the ones already claimed, rather than waiting. It's not a general substitute for either strategy, but it's the right tool for one specific shape of problem — a worker queue pulling jobs from a shared table, where you want pessimistic exclusivity on whichever row you get but zero interest in waiting for a row someone else already grabbed.
The practical rule I'd apply, and the one that matches what the primary sources on both engines converge on: default to optimistic locking for anything read-heavy where conflicts are occasional, because the absence of blocking is worth more than the occasional retry. Reach for pessimistic locking specifically for the rows you already know are hot — a counter, a queue head, a singleton config row — and when you do, sort your lock acquisition order across every code path that touches those rows, because that one discipline is what actually determines whether you see deadlocks in production or just read about them.